Recipes
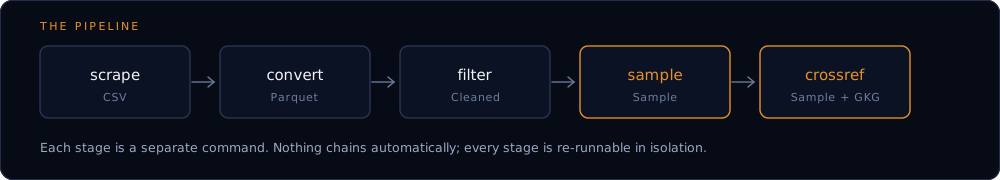
Practical, runnable sampling recipes, assuming you've already run:
gdeltforge scrape --dataset events
gdeltforge convert --dataset events
gdeltforge filter --dataset events
Random global samples
Sweep a range of sample sizes in one pass:
mkdir -p samples
for n in 100000 150000 200000 250000 300000 350000 400000 450000 500000; do
    gdeltforge sample --dataset events --mode indexed -n "$n" --out "samples/sample_${n}.parquet"
done
Reproducible run: the same seed always produces the same rows, useful for sharing a dataset others can regenerate exactly:
gdeltforge sample \
  --dataset events \
  --mode indexed \
  -n 500000 \
  --seed 42 \
  --out samples/reproducible_500k.parquet
Calendar samples
A fixed number of rows per period, across the whole period your downloaded data covers:
for d in 2 3 4 5; do
    gdeltforge sample --dataset events --mode calendar --per-period "$d" --out "samples/daily_${d}.parquet"
done
Country-filtered dataset
Combine an OR block across every column that can carry a country code to catch all Brazil-related events, regardless of which actor or location field it showed up in:
gdeltforge sample \
  --dataset events \
  --mode filtered \
  --filter '{ "OR": { "Actor1CountryCode": "BRA", "Actor2CountryCode": "BRA", "Actor1Geo_CountryCode": "BR", "Actor2Geo_CountryCode": "BR", "ActionGeo_CountryCode": "BR" } }' \
  -n 100000 \
  --out samples/brazil_100k.parquet
Slim version: keep only the columns you actually need, which keeps memory use down on large samples:
gdeltforge sample \
  --dataset events \
  --mode filtered \
  --filter '{ "OR": { "Actor1CountryCode": "BRA", "Actor2CountryCode": "BRA", "ActionGeo_CountryCode": "BR" } }' \
  --columns GlobalEventID Year MonthYear Day Actor1Code Actor2Code QuadClass GoldsteinScale AvgTone ActionGeo_CountryCode \
  -n 100000 \
  --out samples/brazil_slim_100k.parquet
Stratified samples
Stratified sampling draws exactly N rows per distinct value of a chosen column, producing a class-balanced dataset regardless of natural event frequencies; see Filtered Sampling for the full filter syntax these combine with.
50k events per QuadClass (4 classes -> 200k total rows):
gdeltforge sample \
  --dataset events \
  --mode filtered \
  --stratify QuadClass \
  --n-per-group 50000 \
  --out samples/stratified_quadclass_50k.parquet
Brazil events balanced by event type:
gdeltforge sample \
  --dataset events \
  --mode filtered \
  --filter '{ "ActionGeo_CountryCode": "BR" }' \
  --stratify QuadClass \
  --n-per-group 25000 \
  --out samples/brazil_stratified_quadclass.parquet
Verbal events (QuadClass 1 or 2) balanced by root-event flag:
gdeltforge sample \
  --dataset events \
  --mode filtered \
  --filter '{ "QuadClass": [1, 2] }' \
  --stratify IsRootEvent \
  --n-per-group 50000 \
  --out samples/verbal_stratified_rootflag.parquet
GKG-enriched events
Sample Events, then enrich the sample with GKG (themes, tone, people, organizations) via crossref. GKG 2.1, the current format, carries no event ID at all, only the source article's URL, so it needs Mentions too, as the bridge to Events; legacy GKG 1.0 carries EventIds directly, so it skips straight to GKG. See Comparison for why that two-hop join is worth a dedicated command rather than a one-line dataframe merge.
GKG 2.1 (live since Feb 2015, updated every 15 minutes):
gdeltforge scrape --dataset gkg-v2 --start-date 2020-01-01 --end-date 2020-01-31
gdeltforge scrape --dataset mentions --start-date 2020-01-01 --end-date 2020-01-31
gdeltforge convert --dataset gkg-v2
gdeltforge convert --dataset mentions
gdeltforge filter --dataset gkg-v2
gdeltforge filter --dataset mentions

gdeltforge sample --dataset events --mode indexed -n 5000 --seed 42 --out samples/events_5k.parquet

gdeltforge crossref \
  --events samples/events_5k.parquet \
  --gkg-version v2 \
  --out samples/events_gkg_5k.parquet
GKG 1.0 (legacy: the primary feed April 2013 through February 2015, still published daily since for backwards compatibility) is a direct join, no Mentions needed:
gdeltforge scrape --dataset gkg-v1 --start-date 2020-01-01 --end-date 2020-01-31
gdeltforge convert --dataset gkg-v1
gdeltforge filter --dataset gkg-v1

gdeltforge crossref \
  --events samples/events_5k.parquet \
  --gkg-version v1 \
  --out samples/events_gkgv1_5k.parquet
Both preserve the real many-to-many structure rather than collapsing it: one event can produce several output rows (one per article that covered it), and one article covering several events contributes one row per event.
GKG-enriched events across the 2013-2015 boundary
GKG 2.1 and Mentions don't exist before GDELT 2.0 launched, 2015-02-18; GKG 1.0 has been live since 2013-04-01 and is still published today. A sample spanning that boundary can't use a single --gkg-version for the whole thing: v1 alone misses GKG 2.1's richer per-article fields for the post-2015 portion, and v2 alone finds nothing at all for the pre-2015 portion. --gkg-version auto attempts every eligible event against both generations instead, rather than picking exactly one per event by its DATEADDED: a Mentions row is timestamped by when it was created, not by its event's DATEADDED, so a pre-2015 event can still have a real GKG 2.1 match created much later, and a post-2015 event isn't guaranteed to miss GKG 1.0 either, since it's still being published today.
# GKG 1.0 covers the whole window; GKG 2.1 + Mentions only from 2015-02-18 on.
gdeltforge scrape --dataset gkg-v1 --start-date 2014-01-01 --end-date 2016-01-01
gdeltforge convert --dataset gkg-v1
gdeltforge filter --dataset gkg-v1

gdeltforge scrape --dataset gkg-v2 --start-date 2015-02-18 --end-date 2016-01-01
gdeltforge scrape --dataset mentions --start-date 2015-02-18 --end-date 2016-01-01
gdeltforge convert --dataset gkg-v2
gdeltforge convert --dataset mentions
gdeltforge filter --dataset gkg-v2
gdeltforge filter --dataset mentions

gdeltforge filter --dataset events --start-date 2014-01-01 --end-date 2016-01-01
gdeltforge sample \
    --dataset events \
    --mode filtered \
    --filter '{"DATEADDED": {"op": "between", "min": 20140101, "max": 20160101}}' \
    -n 5000 --out samples/gap_events_5k.parquet

gdeltforge crossref \
    --events samples/gap_events_5k.parquet \
    --gkg-version auto \
    --out samples/gap_events_enriched_5k.parquet
Output carries a CrossrefSource column (v1 or v2) marking which generation actually produced each row. Most events will still end up dominated by one generation in practice (an event dated well before 2015-02-18 is far more likely to have GKG 1.0's coarser, day-aggregated fields, GKG_Themes, GKG_Date, ..., than a GKG 2.1 match), but this isn't enforced or assumed: an event genuinely covered by both generations contributes one row per generation, not a merged or arbitrarily-dropped row, and one covered by only the "wrong" generation for its date (e.g. a pre-2015 event re-covered by an article well after GKG 2.1 launched) still finds that match instead of it being silently unreachable. The two schemas don't overlap at all, so a row carries NaN for whichever set its source generation didn't produce, not a forced or incorrect merge. Any event in the sample dated before 2013-04-01 has no match in either generation and is skipped with a warning rather than silently dropped.