Getting Started
Installation
pip install gdeltforge
uv pip install gdeltforge
Verify it installed:
gdeltforge --help
Installing from source
Only needed if you're contributing to GdeltForge itself, or want an editable install
# Install uv (if not already installed)
pip install uv

git clone https://github.com/Vinicius-Teixeirac/GdeltForge.git
cd GdeltForge

# Create the virtual environment, install dependencies, and install
# GdeltForge itself (editable): this is what makes the `gdeltforge`
# command available.
uv sync

# Activate the virtual environment
# Windows
.venv\Scripts\activate
# macOS / Linux
source .venv/bin/activate

# Verify the CLI is installed
gdeltforge --help
python main.py <command> also works as a backward-compatible alias for the gdeltforge command, in case you have existing scripts built around it. This alias is only present in a source checkout, not in the PyPI package.
Configuration
Optional: skip this and everything below still runs
GdeltForge falls back to a conservative built-in default (real ./data/... paths, no row/column filtering) if there's no config file, and writes that default to config/settings.yaml on first run. A fresh environment (a Colab session, say) works with nothing configured.
Worth doing anyway for a real project, so you're deciding paths: and filter.columns_to_check deliberately rather than accepting the defaults:
cp config/settings.example.yaml config/settings.yaml
At minimum, review paths: (where downloaded/converted/filtered data will live) and filter.columns_to_check (which columns must be non-null for a row to survive filtering). See the full Configuration reference for every option, including what the built-in fallback actually sets.
Your first pipeline run
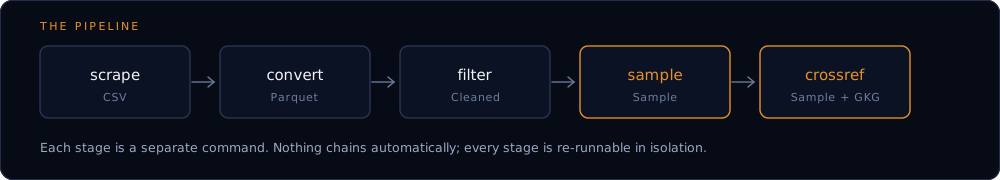
Each stage is a separate command, run in order. A small, date-restricted run is the fastest way to confirm everything is wired up correctly:
gdeltforge scrape --dataset events --start-date 2024-01-01 --end-date 2024-01-07
gdeltforge convert --dataset events
gdeltforge filter --dataset events
gdeltforge sample --dataset events --mode indexed -n 1000 --out sample.parquet
This downloads one week of daily GDELT files, converts them to Parquet, drops rows missing your configured columns, and writes a 1,000-row random sample to sample.parquet.
Once that works, drop the date flags to work with the full archive (1979-present).
The full archive is big
Dropping the date flags means thousands of files and hundreds of GB. Try --dry-run first to see how many files a scrape would pull, and see Capacity planning for measured sizes per dataset.
Running the test suite
The test suite is pure unit tests: no network access, no browser, no real GDELT data required.
uv sync --group dev
uv run pytest
Building the docs locally
This site is built with MkDocs + the Material theme.
uv sync --group docs
uv run mkdocs serve
Then open http://127.0.0.1:8000/.
Where to go next
CLI Reference →
Every command, every flag, with examples.
Recipes →
Runnable, end-to-end workflows.
Filtered Sampling →
The complete filter syntax.
Configuration →
The full settings.yaml reference.
Crossref Semantics →
What the Events<->GKG join really produces.
Comparison →
When another tool is the better choice.